Auditing BixBench: Broken Tasks and Faulty Judging Hide Saturation

Flawed tasks and grading errors conceal how well agents perform. Correcting them raises measured performance by up to 42 percentage points.
Read the postFlawed tasks and grading errors conceal how well agents perform. Correcting them raises measured performance by up to 42 percentage points.
Read the post
With a larger inference budget, GLM-5.3-Flash matched Mythos Preview on ExploitBench at about 6% of the cost.
Read the post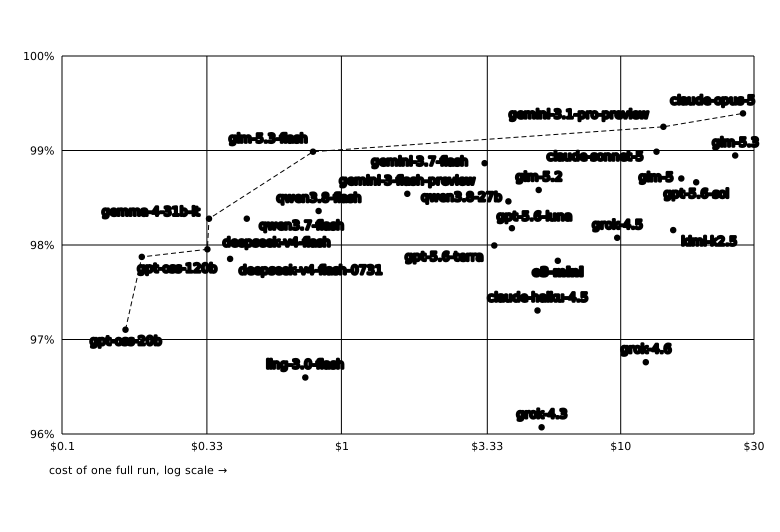
Choosing a new grader for HLE: comparing judge accuracy and cost against a panel of frontier models.
Read the post
Can we forecast when AI agents will complete real-world work? New methods for predicting performance on the Remote Labor Index.
Read the postWe're an R&D lab that solves practical challenges facing AI safety organisations, focusing on AI evaluation.
We provide:
Research services for organisations that want quick access to AI evaluation expertise
Tools & infrastructure that expand access to high-quality data and measurement tools
Research infrastructure
We actively maintain 100+ eval implementations in the Inspect Evals repository. They've been used in dozens of research projects and testing exercises.
We recently built the Inspect Evals Register, making it easier than ever to find and share Inspect Tasks.
Research service
With AI safety orgs scaling up and moving fast, it's important to maintain the highest possible standards when measuring and reporting risks.
We provide 3rd-party audits for evals, helping research teams catch issues early and maintain trust.